TL;DR AI agents become expensive when they keep working after they stop making progress. Better prompts can reduce mistakes, but they cannot enforce a budget or guarantee that a run will stop. Production systems need hard limits on turns, tokens, cost, elapsed time, and repeated actions. Those checks must run in code before the next model call or paid tool invocation. This article uses circuit breaker as an umbrella term for those enforced stops. Together they give an open-ended loop a predictable worst-case cost.
The problem: agents fail quietly
Conventional software often announces failure with an exception or crash. An agent can fail while appearing busy. It calls a tool, receives an ambiguous result, tries again, and repeats without moving closer to the goal. \n\n\nEach model invocation and paid tool call adds cost. The control loop may be working as designed; the failure is that nothing independent can refuse another attempt. This makes the trace look healthier than the outcome. \n\n\nRequests succeed, tools return valid responses, and workers remain active, yet the task state barely changes. A system that treats successful API responses as progress can therefore miss the most expensive kind of failure.
In simple agent architectures, later model requests often resend much of the earlier context. Input tokens can grow with each turn, so cumulative cost may rise faster than the turn count. A late retry may cost more than an early one because it carries the accumulated conversation, tool results, and planning notes. \n\n\nResponse chaining, prompt caching, compaction, and selective memory can reduce that effect, but they do not bound the run. They also introduce their own failure cases: a summary can omit the fact that an action already failed, while retained tool output can keep an irrelevant branch alive. Long prompts, expensive models, paid tools, and parallel workers can therefore accumulate substantial spend before anyone checks the billing dashboard.
Practitioners report this failure mode regularly. In one popular r/AI_Agents thread, an agent retried the same failed tool call overnight and accumulated about £220 in charges. Commenters recommended per-agent budgets, caps on identical calls, tracing, and kill switches. These reports are anecdotes rather than controlled evidence, but they show the operational problem: a run can remain active and billable after it stops producing useful work.
Why smarter prompts do not fix this
When an agent overspends, adding an instruction to be careful with money may seem like the obvious fix. It can improve behavior, but it cannot provide a hard guarantee. The model may still interpret another retry as reasonable. A budget written in the prompt is guidance. A budget checked by code can refuse the next call, even when the model believes it should continue.
Monitoring does not stop a runaway run either. Logs and dashboards are useful, but they act after requests have been made. A widely repeated account on DEV Community describes four agents looping for eleven days and accumulating a forty-seven-thousand-dollar bill. \n\n\nThe available write-ups do not identify the affected team or link to a first-party postmortem, so treat the amount as unverified rather than as a documented industry incident. The underlying distinction remains sound: observability records activity and supports diagnosis; enforcement blocks the next chargeable action before more money is spent.
The stopping mechanism therefore has to sit on the execution path and evaluate the run before another chargeable action begins. Prompts guide decisions, while logs and dashboards support diagnosis; neither can deny the next call. The same rule applies to paid tools because an agent can overspend through either route.
How to do it in practice
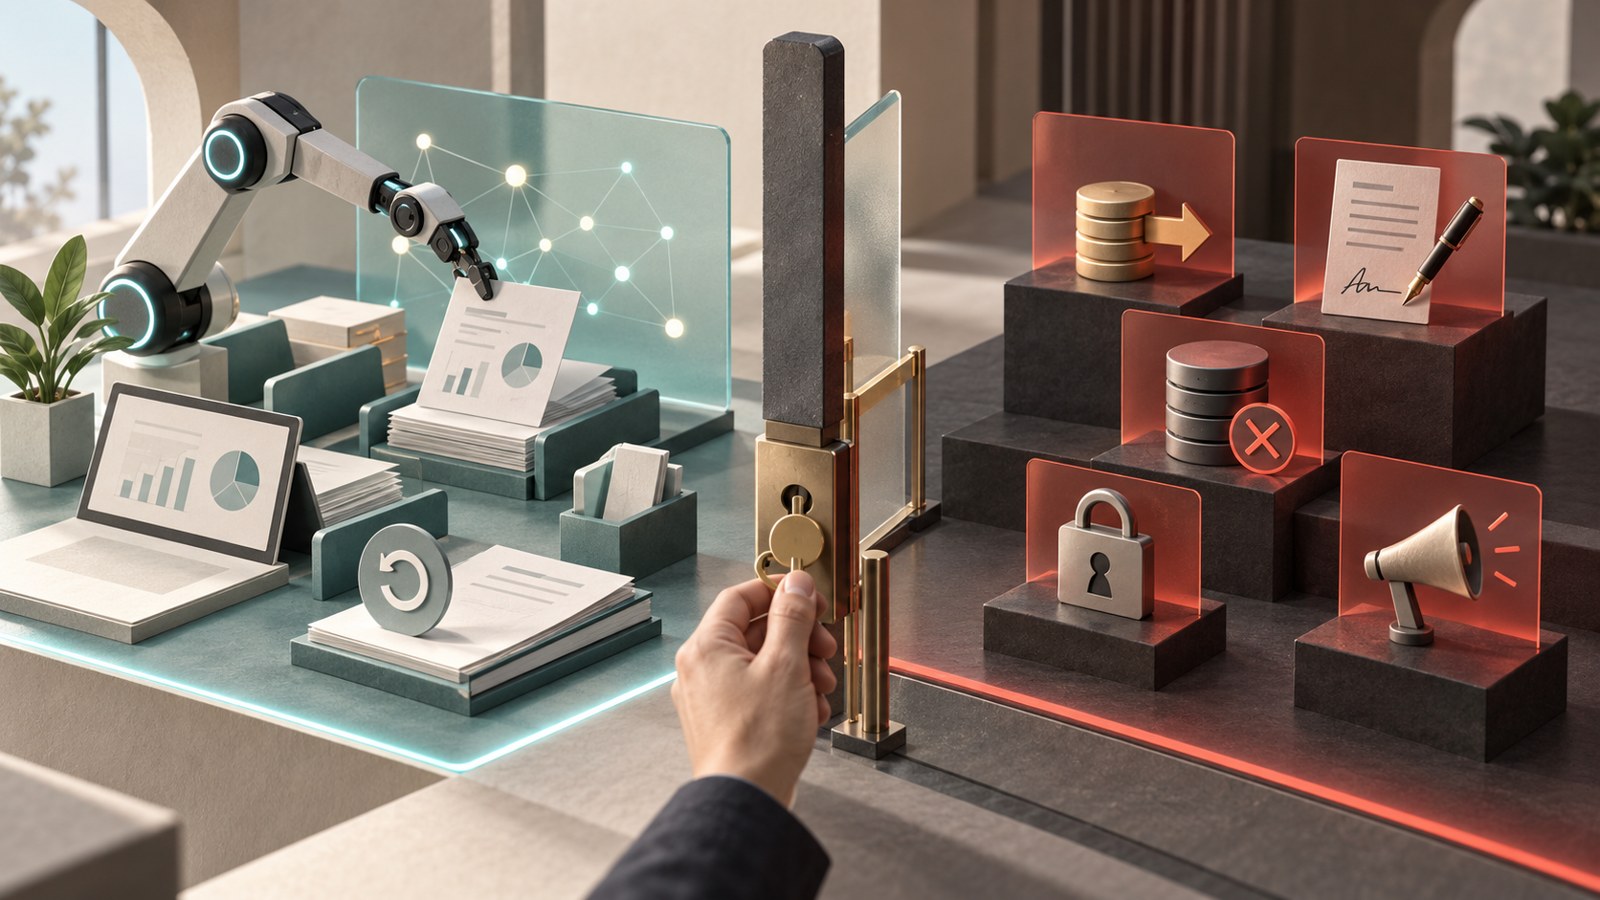
The practical version is a set of layered limits. You do not need every layer on day one, but each production run needs a hard upper bound. Add the controls in this order, then tune them from observed healthy runs. The goal is to ensure that even an unfamiliar failure has a finite cost and a clear stopping point.
1. Set a step limit first.
A step limit caps one framework-specific unit of work. LangGraph's recursion_limit bounds graph steps. The OpenAI Agents SDK's max_turns bounds model invocations, which may include tool calls. CrewAI and AutoGen expose related iteration or reply controls. \n\n\nThese settings do not count exactly the same thing, and their defaults can change. Set an explicit value using primary documentation for the version you deploy. Choose a ceiling above healthy runs, test how the framework reports a trip, and investigate unexpected trips instead of retrying automatically. A limit that silently restarts the workflow does not bound the overall job.
2. Add a token and dollar ceiling per task.
A step cap bounds iterations, not spend. One step can be expensive when the prompt is large, the model is costly, a paid tool is involved, or workers run in parallel. Add run-level token and dollar ceilings. Before each chargeable action, reserve a conservative estimate against the remaining budget. Refuse the action if that reservation would cross the ceiling, then reconcile the estimate with actual usage. For example, if a run has eighty cents left and the next request may cost up to one dollar, the system should stop before sending it. Waiting for the final usage record would allow the budget to be exceeded. Reservations must be atomic under concurrency so several workers cannot spend the same remaining balance. Release unused reservations when a request fails before billing or costs less than estimated. Size the ceiling from observed healthy tasks plus a deliberate margin, and use a parent budget to bound delegated agents as a group.
3. Detect the loop, not just the length.
A plain counter cannot distinguish a productive run from a stuck one. The next layer looks for repeated state: the same tool and arguments, nearly identical requests, or no meaningful change in output. \n\n\nApply these checks after the approved retry policy because a repeated call can be legitimate. Normalize volatile fields such as timestamps and request identifiers before comparing actions, and allow explicit exceptions for polling. Similarity checks work best as an escalation ladder: warn on the first suspicious repeat, require a changed plan after the next one, and stop when the configured threshold is reached. Record the normalized signature and the rule that triggered the stop so the owner can distinguish a loop from a false positive.
4. Add a wall clock limit and a no progress check.
Tokens are not the only resource that can run away. Use a wall-clock deadline for the run, request-level timeouts, and cancellation that propagates to workers and tools. The request timeout should be shorter than the run deadline so the controller still has time to record the failure and cancel dependants. \n\n\nStopping the parent while child jobs continue does not contain cost. A no-progress check also needs a task-specific metric: new evidence for a search agent, for example, or a state transition for a workflow. Define the metric before deployment and test it against successful but slow cases. Stop and checkpoint the run when that metric fails to improve across a defined number of checks.
5. Decide where the breaker lives.
These controls usually live in two places. A shared gateway can enforce organization-wide budgets and rate limits. Run-level logic sees task state and can detect repeated actions, no progress, or one unhealthy workflow. Many systems use both. The two layers need a common run identifier so a gateway denial can be traced back to the workflow that caused it. They also need a clear precedence rule: the narrowest remaining budget should govern the next call, while broader team and organization limits remain backstops. This article uses circuit breaker broadly; in classic software, the term more specifically means opening after repeated downstream failures and later testing recovery. Whatever name you choose, the control must block the next chargeable action and identify the responsible run. A monthly provider cap is useful as a backstop, but too coarse to protect one task, customer, or team.
6. Fail in a way that a human can act on.
When a breaker trips, stop cleanly, save a checkpoint, and send one useful alert. Include the run identifier, owner, rule that tripped, amount spent, configured limit, elapsed time, and last action. Preserve the trace and enough state to reproduce the decision without recording unnecessary sensitive data. \n\n\nThe resume path should be idempotent: restoring the checkpoint must not repeat a completed payment, message, write, or other side effect. Inspect the evidence before raising a limit, then resume only when the next action is understood and the cause of the stop has been addressed. This creates a bounded failure with a clear recovery path instead of a hurried override that restarts the loop.
You do not need to build every control from scratch. Some libraries, gateways, and orchestration frameworks provide budget checks, iteration limits, or loop detection, although their guarantees differ. The floe-guard project page documents one pre-call reservation pattern for enforcing a dollar ceiling. The catalog of agent failure case studies on GitHub is useful for finding examples, but follow each case back to its original evidence before relying on a headline number. Whether you adopt a library or write a wrapper, test concurrency, estimation error, streaming usage, delegated agents, and paid tools. Test the failure path as deliberately as the successful one: simulate a stale price table, an unavailable usage endpoint, a worker that ignores cancellation, and a request that finishes after its reservation expires. Decide in advance which failures must stop closed and which can continue under a smaller emergency allowance. A simple running counter can otherwise be bypassed or report the final cost only after the budget has been exceeded.
Why this is the current advice
Hard runtime limits are a recurring recommendation across framework documentation, incident catalogs, vendor engineering posts, and practitioner discussions, but those sources do not establish a formal industry consensus. A roundup of ten Reddit threads from May 2026 is a snapshot of current concerns, not proof of industry consensus. Stronger support comes from termination controls in major frameworks and a 2026 preprint cataloging 63 reported budget-overrun incidents, with stated limitations. \n\n\nThe implementation is direct: before each chargeable action, check the step count, deadline, repetition signature, and remaining budget; reserve estimated cost atomically; make the call; then record and reconcile actual usage. If a rule trips, cancel downstream work, checkpoint the state, send one structured alert, and require an explicit decision before resuming. Layer limits from the request to the organization so a local bug cannot consume a shared budget.
There is also a business case for these controls. In June 2025, Gartner predicted that more than 40% of agentic AI projects would be cancelled by the end of 2027, citing escalating costs, unclear value, and inadequate risk controls. \n\n\nA runaway bill does not prove that a project lacks value, but it can end a pilot before the team measures that value. Per-run limits reduce that avoidable risk and make worst-case exposure easier to explain. They also make experiments easier to compare because each run operates inside a known cost envelope. Teams can then evaluate completion rate, quality, latency, and cost per successful task without a handful of uncontrolled runs distorting the result.
Where the limits sit in an agent run
| Control | What it bounds | Where it runs | Typical trip signal |
|---|---|---|---|
| Step limit | Framework steps or model turns | Run-level orchestration | Recursion or max-turn error |
| Token and dollar ceiling | Spend per task, including paid tools | Pre-call reservation in code | Reservation would cross the ceiling |
| Repetition check | Identical or near-identical actions | Run-level, after the retry policy | Normalized action signature repeats |
| Wall clock and no-progress | Elapsed time and task progress | Controller with cancellation | Deadline reached or metric flat |
| Gateway budget | Team and organization spend | Shared gateway | Denied request with run identifier |
The takeaway
For runaway spend, production reliability is primarily an operations and control problem. Prompts can reduce unnecessary behavior, but they cannot guarantee a bounded bill. Limit each run's steps, tokens, cost, repetition, and elapsed time. \n\n\nEnforce those limits before the next chargeable action, preserve enough state to diagnose a stop, and require a deliberate decision before resuming. Review limit trips as reliability events, not merely billing anomalies, because each one reveals a mismatch between expected and actual execution. \n\n\nA useful limit is high enough for normal work, low enough to cap an accident, and visible enough that its owner can explain it. Broader ceilings provide additional backstops. These controls do not make an agent correct or replace observability; they make failure bounded, attributable, and recoverable.
If you are putting agents into production, our teams can help you scope these controls: see AI Agents & MCP Development and AI Readiness Audit.
Resources
- LangGraph recursion limit documentation (LangChain official docs). Defines the graph step limit and how to change it.
- AutoGen conversation termination guide (Microsoft official docs). Covers max_turns and termination messages.
- Agent loop termination patterns (Agent Native). A secondary comparison; verify defaults in primary documentation.
- Rate limiting AI agents at the gateway (TrueFoundry engineering blog). A gateway vendor's view of centralized enforcement.
- OpenAI Agents SDK Runner documentation (OpenAI official docs). Defines max_turns and what counts as a turn.
- CrewAI agent configuration (CrewAI official docs). Documents max_iter and related execution controls.
- AI agent cost governance (iSimplifyMe). Discusses budget sizing and layered controls.
- Token Budgets: an empirical catalog of budget overrun incidents (arXiv preprint). An academic catalog that classifies framework step counters as structural limits rather than true cost caps. Treat as a preprint that supports the other sources.